DeepSeek-V4-Flash-0731 keeps the same architecture and size as the preview model, but the jump in agentic performance is hard to treat as a normal update.
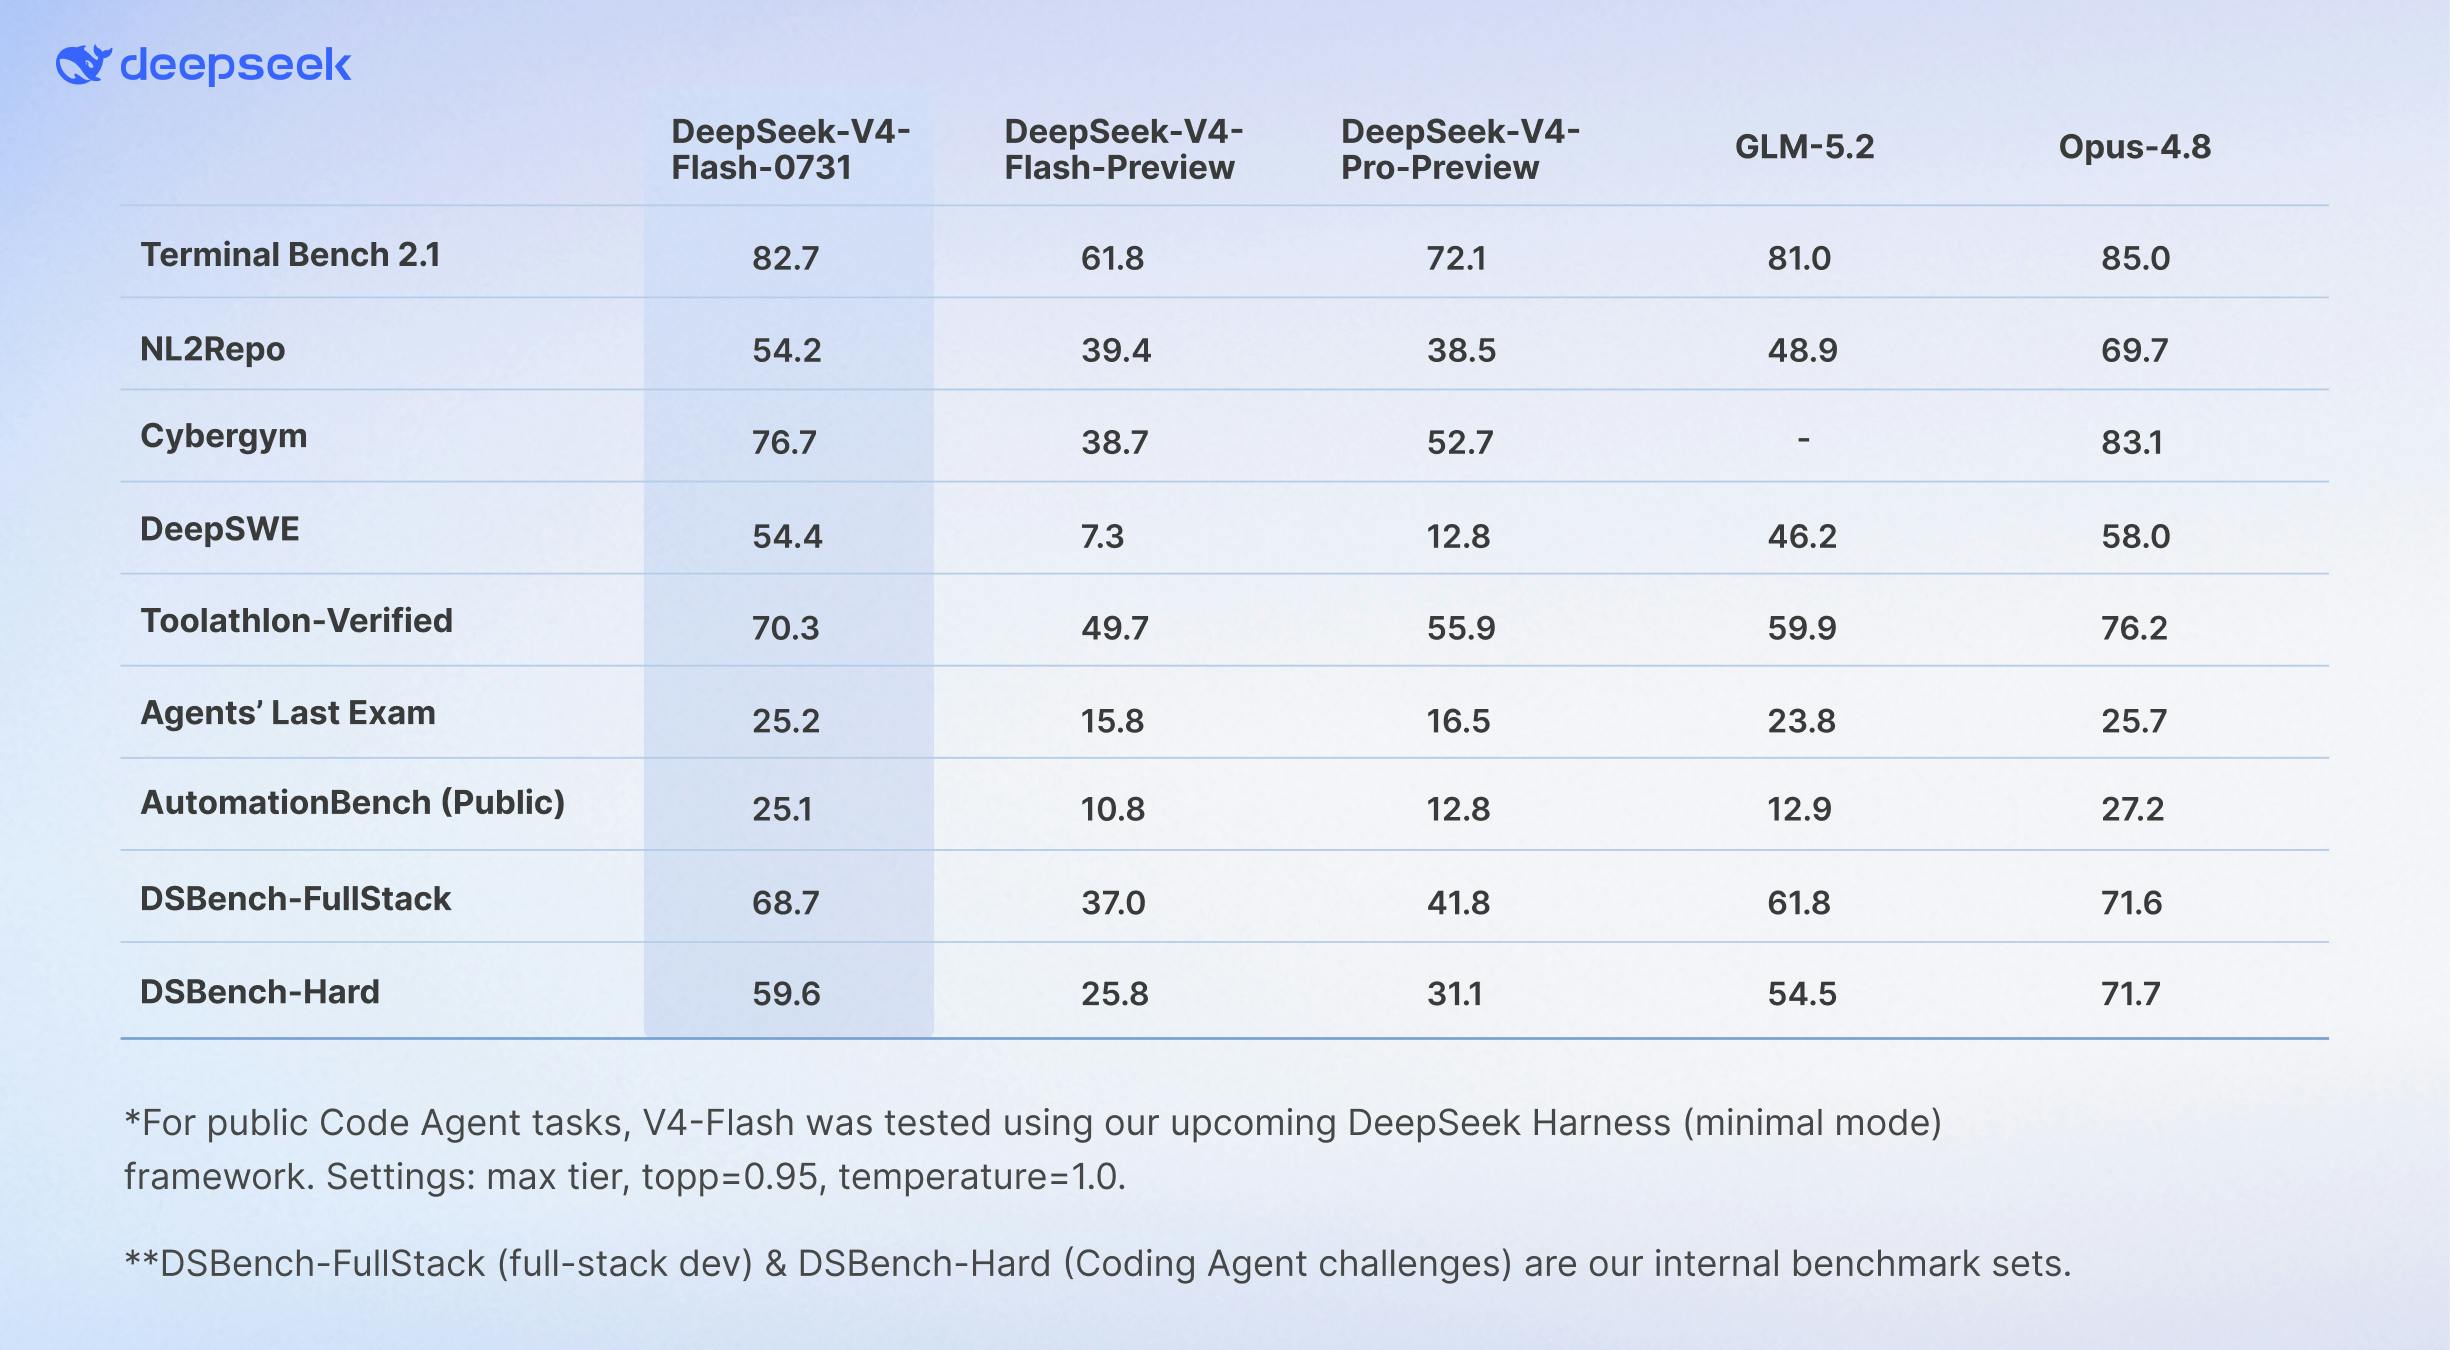
Terminal-Bench 2.1 moved from 61.8 to 82.7. DeepSWE went from 7.3 to 54.4 (simply CRAZY). Flash now beats V4-Pro Preview on every benchmark shown in DeepSeek’s release table, while activating far fewer parameters.
The weights and inference code are already available under MIT too, so this is not just an API release.
Then there is the price. V4 Flash currently costs $0.14 per million uncached input tokens and $0.28 per million output tokens. GPT-5.6 Terra and Luna also just got much cheaper.
Top-tier intelligence is becoming extremely cheap. I mean extremely cheap.
I think we are entering a different phase of AI. When intelligence at this level is almost free and available through Codex, what will you build? How far can your imagination go when the cost of trying is no longer the main constraint??
P.S. one slightly crazy hint👀👀:
PH 用户
Is this becoming a price match, Oai also reduced a lot on their frontier models..
PH 用户
61.8 to 82.7 on Terminal-Bench and 7.3 to 54.4 on DeepSWE for a model that's "the same architecture and size" as the preview is the kind of jump that makes me want to know who ran the eval, not just what it scored. are these numbers reproduced by anyone outside DeepSeek yet, or is it still first-party only? weights being MIT and downloadable makes independent verification actually possible here, unlike a closed API release, so I'd rather wait for someone else's harness to confirm it than take the release table at face value.
PH 用户
The number I care about isn't $0.14 per million, it's cost per completed task. A cheaper model that needs two retries on an agent run costs more than a pricier one that lands it first, which is why 61.8 to 82.7 on Terminal-Bench is the line that actually moves my bill. Where it gets interesting is cached input pricing, since on long agent loops most of my spend is context I'm re-sending, not new tokens.
PH 用户
This is likely the most cost efficient model right now, works better than kimi 2.7code, and def better option than gemini flash. 5.6 Luna and Grok build 0.1 are both very good as well
This is another @DeepSeek moment.
DeepSeek-V4-Flash-0731 keeps the same architecture and size as the preview model, but the jump in agentic performance is hard to treat as a normal update.
Terminal-Bench 2.1 moved from 61.8 to 82.7. DeepSWE went from 7.3 to 54.4 (simply CRAZY). Flash now beats V4-Pro Preview on every benchmark shown in DeepSeek’s release table, while activating far fewer parameters.
The weights and inference code are already available under MIT too, so this is not just an API release.
Then there is the price. V4 Flash currently costs $0.14 per million uncached input tokens and $0.28 per million output tokens. GPT-5.6 Terra and Luna also just got much cheaper.
Top-tier intelligence is becoming extremely cheap. I mean extremely cheap.
I think we are entering a different phase of AI. When intelligence at this level is almost free and available through Codex, what will you build? How far can your imagination go when the cost of trying is no longer the main constraint??
P.S. one slightly crazy hint👀👀: