I started SpeakoFlow while studying alone for exams. I kept switching between what I was working on and a chatbot tab, and it got old fast. I'd also been paying for dictation software because talking is faster than typing — but it stopped at typing. It couldn't see what I was working on, so I was still explaining context it could have just looked at.
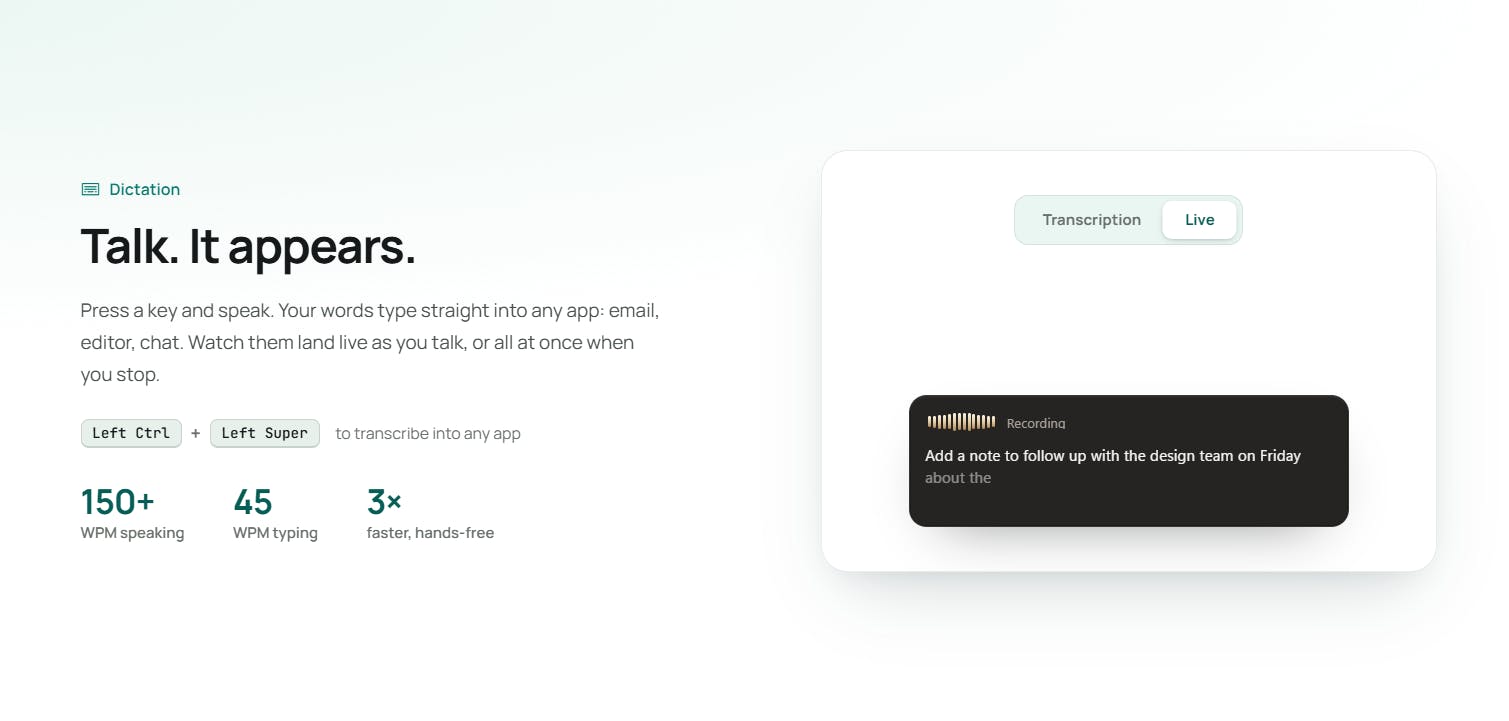
It began as a small dictation tool. Three months later it's a voice layer over my whole desktop: I speak and text lands in any app, I say "Hey Flow" and it writes the whole reply from what's on my screen, and there's an assistant I can open over my work that answers out loud while I keep going.
The thing I care about most is that speech-to-text runs entirely on your own machine. Your voice isn't uploaded anywhere just to become text. For the assistant you choose — a built-in offline model with no API key, your own Ollama or LM Studio, or any cloud provider with your own key.
What I'm really going for is running my computer by voice. The repetitive stuff should be two spoken commands instead of twenty clicks. Not there yet.
It started as a fork of Handy by CJ Pais, and I built the assistant, screen vision, translation and memory on top. Free and MIT licensed — fork it, change it, build something else with it.
It's just me on this and it's early. If you try it and something breaks, tell me here. I'll be around all day.
PH 用户
interesting
PH 用户
Hey ! I wanted to try the app on macos but couldn't download it through your website. it says the file is damaged.
I started SpeakoFlow while studying alone for exams. I kept switching between what
I was working on and a chatbot tab, and it got old fast. I'd also been paying for
dictation software because talking is faster than typing — but it stopped at
typing. It couldn't see what I was working on, so I was still explaining context it
could have just looked at.
It began as a small dictation tool. Three months later it's a voice layer over my
whole desktop: I speak and text lands in any app, I say "Hey Flow" and it writes
the whole reply from what's on my screen, and there's an assistant I can open over
my work that answers out loud while I keep going.
The thing I care about most is that speech-to-text runs entirely on your own
machine. Your voice isn't uploaded anywhere just to become text. For the assistant
you choose — a built-in offline model with no API key, your own Ollama or LM
Studio, or any cloud provider with your own key.
What I'm really going for is running my computer by voice. The repetitive stuff
should be two spoken commands instead of twenty clicks. Not there yet.
It started as a fork of Handy by CJ Pais, and I built the assistant, screen vision,
translation and memory on top. Free and MIT licensed — fork it, change it, build
something else with it.
It's just me on this and it's early. If you try it and something breaks, tell me
here. I'll be around all day.