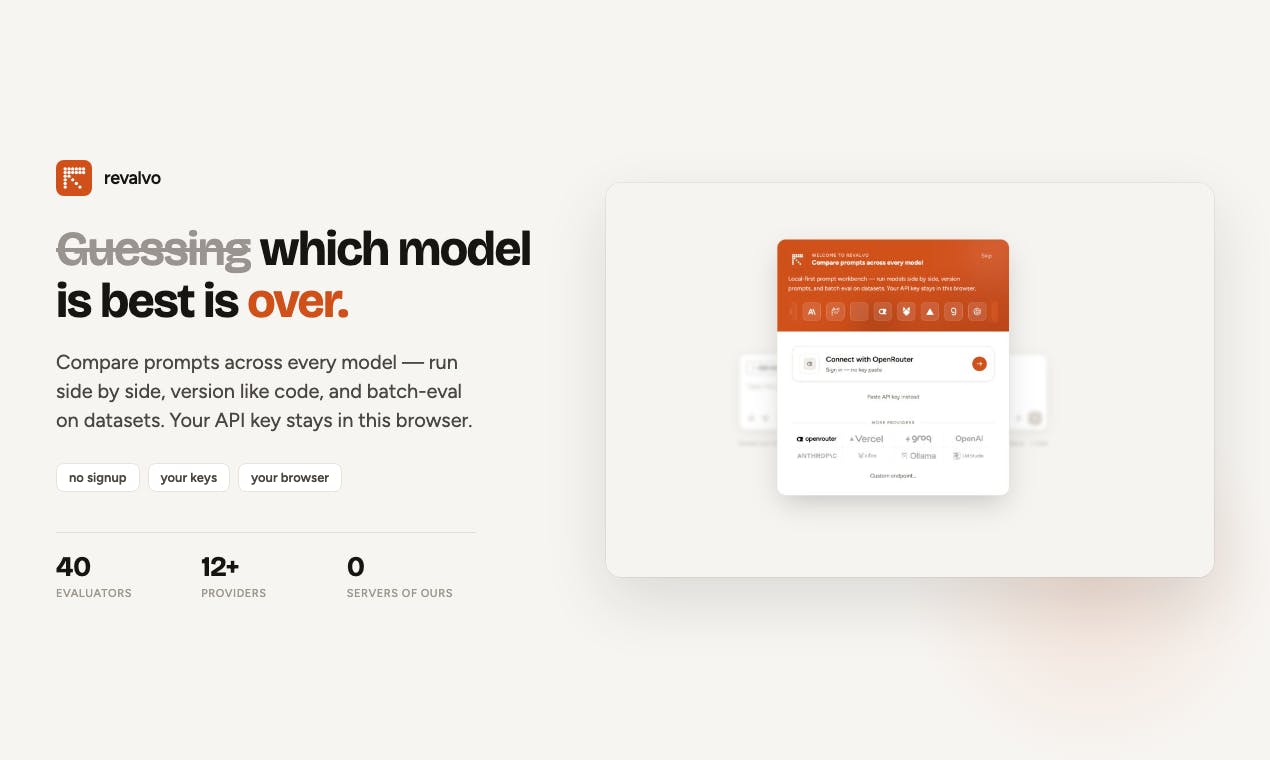
We built Revalvo because chat playgrounds are fast but leave no receipt, and hosted eval platforms are rigorous but slow and server-side. Revalvo sits in the middle: sub-minute setup, side-by-side multi-model runs, git-style versioning, and batch eval in one local-first app.
Try it: revalvo.com — paste an OpenRouter/any OpenAI Compatible providers key or run fully offline with Ollama.
What we’d love feedback on: evaluator coverage, GitHub sync workflow, and which providers you want next.
Built with BYOK — we never touch your keys or markup your API spend.
PH 用户
hey, classic question: how is it different than langsmith evals or weights and biases evals?
PH 用户
40 evaluators is the number I'd push on. Most eval suites I've used come down to another model grading the output, so the eval inherits the same failure mode as the thing it's grading. For each of those 40 I'd want to know upfront whether it's deterministic or a judge model, because I trust those two very differently. BYOK with no markup on API spend is the right call though.
Try it: revalvo.com — paste an OpenRouter/any OpenAI Compatible providers key or run fully offline with Ollama.
What we’d love feedback on: evaluator coverage, GitHub sync workflow, and which providers you want next.
Built with BYOK — we never touch your keys or markup your API spend.