Reflexio 通过记录用户交互反馈,让 AI 智能体持续学习改进行为,适用于开发者,能减少任务失败率。
热门评论
PH 用户
Hey Product Hunt 👋 I'm Yi, co-founder of Reflexio. Before starting Reflexio, I was tech lead in Meta and adjunct professor at University of Washington teaching ML and business applications.
Today we're launching Reflexio: a learning platform that makes your AI agents fail less and burn fewer tokens, by learning from what actually happens in production.
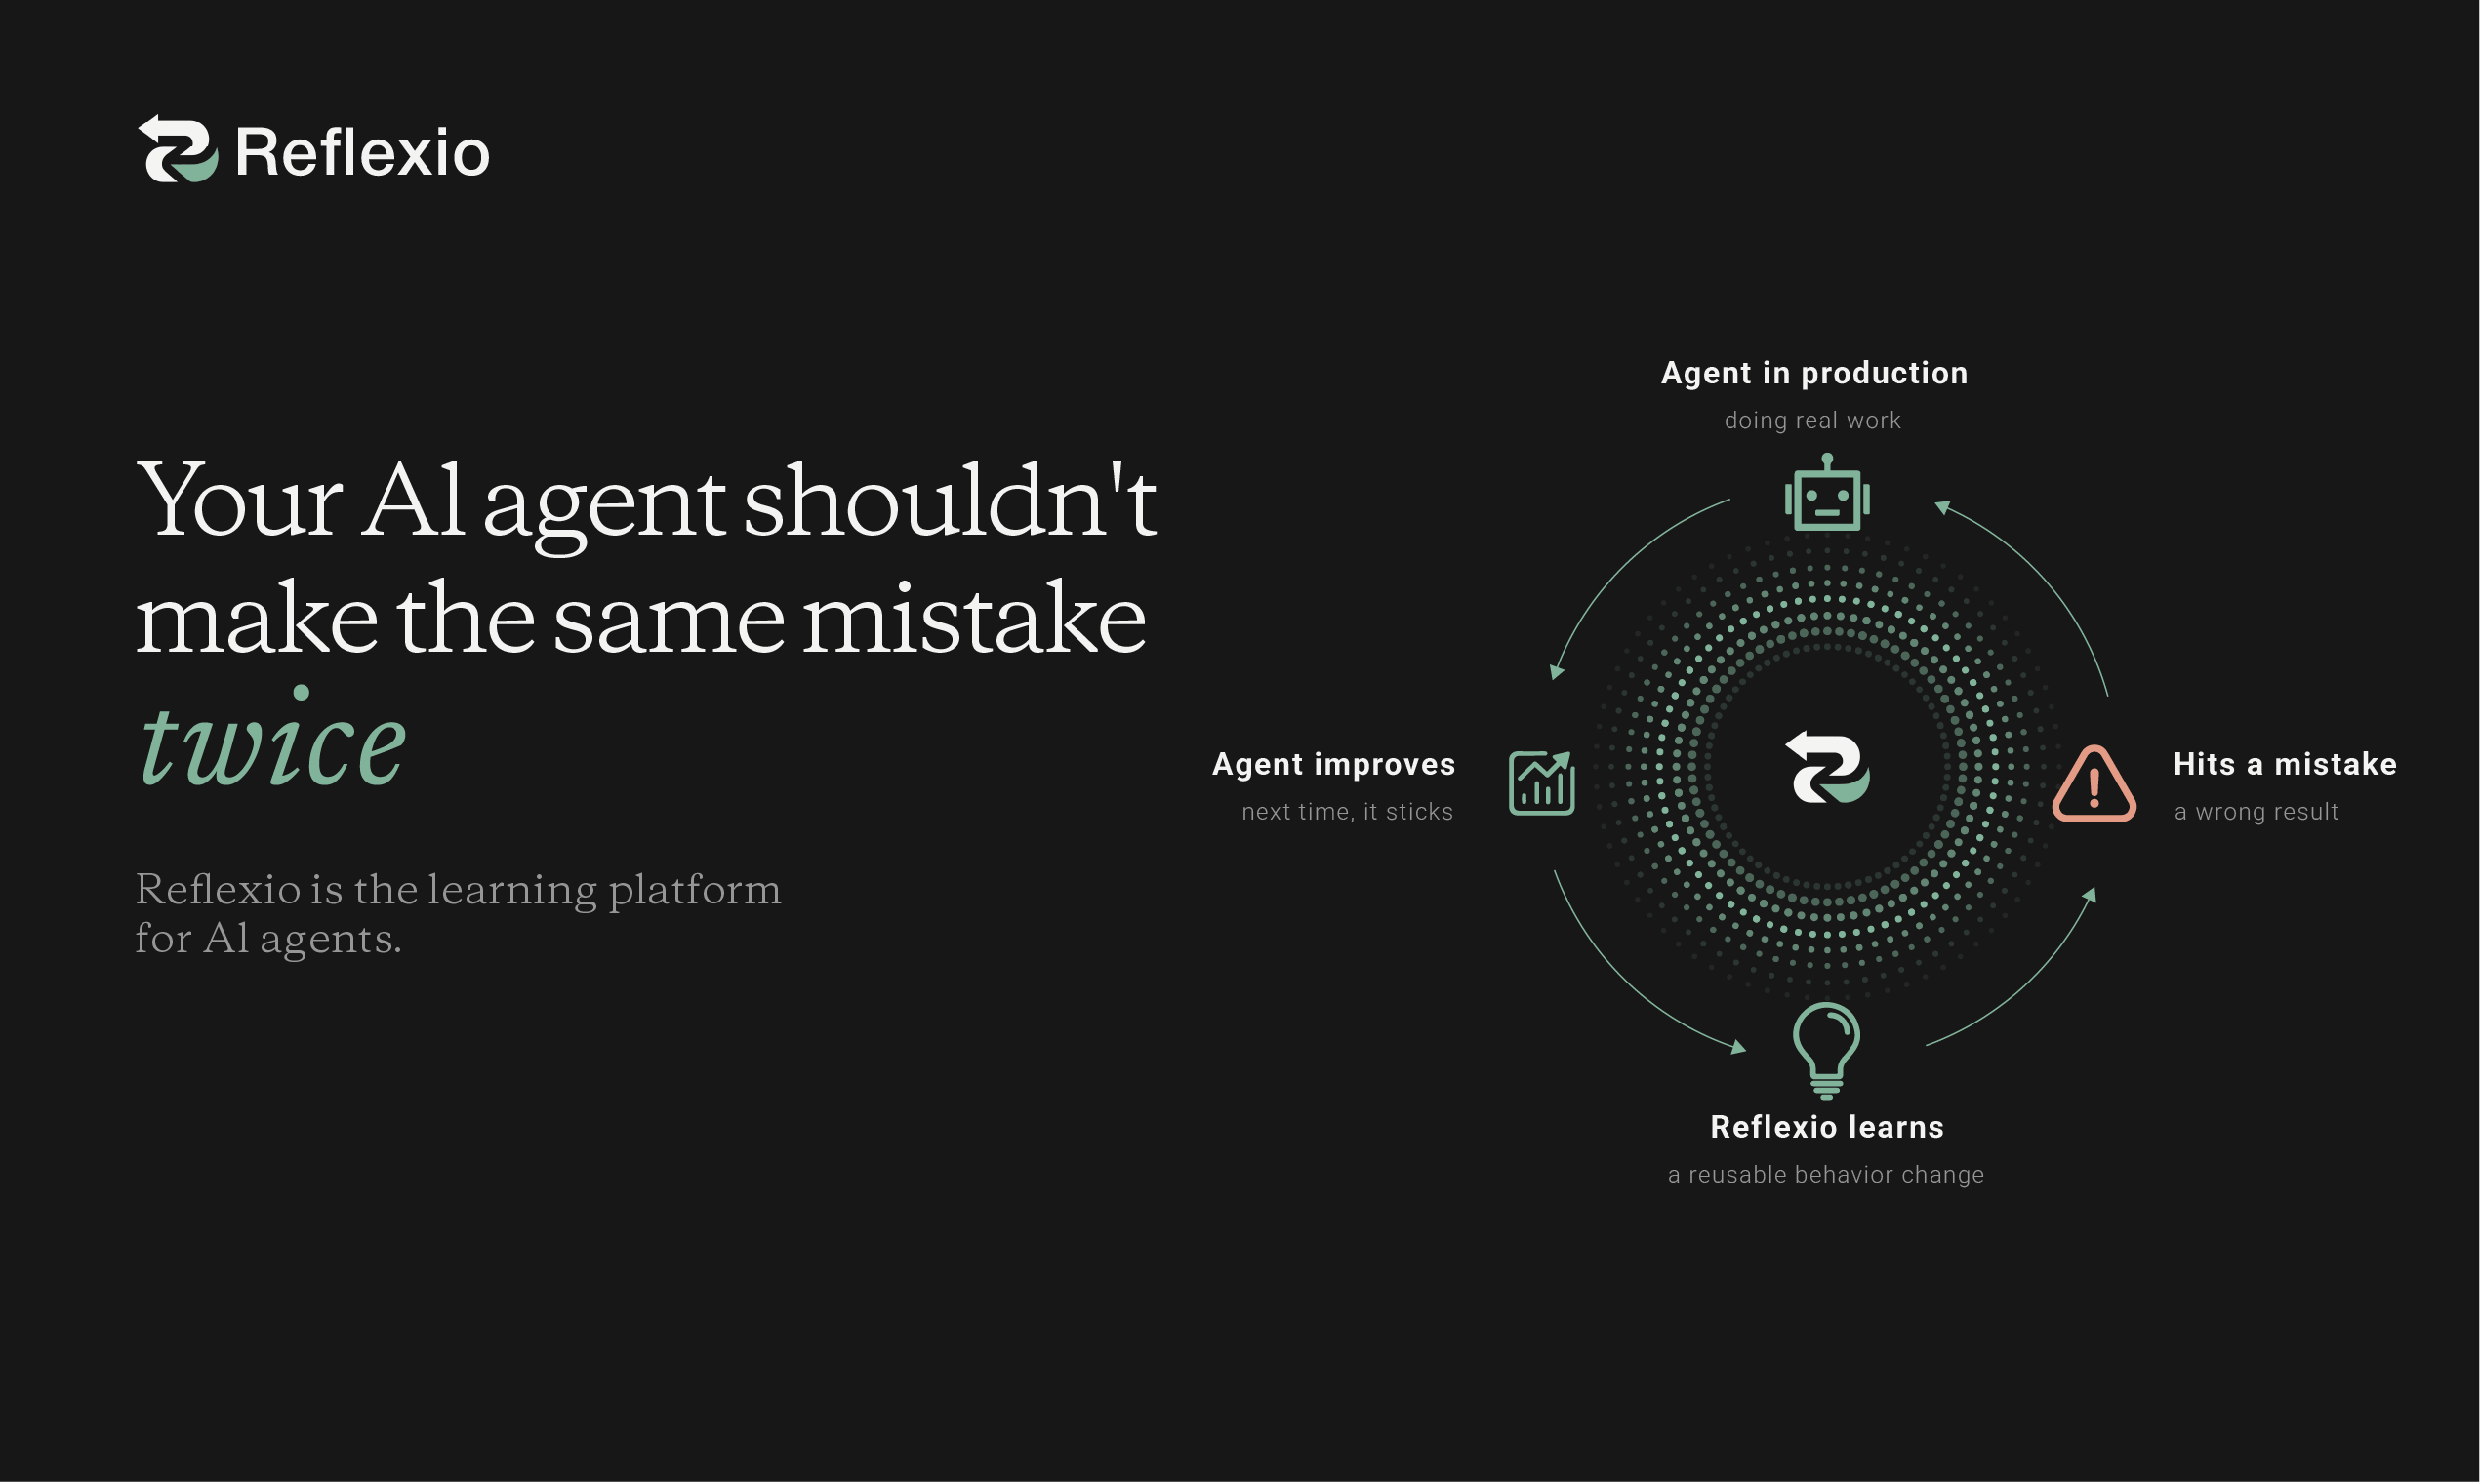
Here's what got us started: people use AI agents every day, but agents never actually get better with use. Even with memory, an agent that failed a task yesterday will fail the same way today, across different users — because nothing connects what happened in production back to how the agent behaves next time. The online learning loop just isn't there.
We learned firsthand that closing that loop manually — reading traces, spotting failures, rewriting prompts — is a painful, never-ending job. Reflexio autonomously observes your agent's live traces, learns from successes, failures, and user corrections, and continuously optimizes behavior. No manual tuning.
The results? In our case studies, agents with Reflexio:🎯 Cut task failure rate by 36%💸 Reduced token usage by 57%📈 Improved response quality in 47% of interactions, with negligible regressions Try it today: sign up free at reflexio.ai and get 30 days of Pro on us.
PH 用户
Hey Yi, congrats on the launch! I totally get how frustrating manual log tracing can be when you are trying to fix those pesky failing prompts in production. I am curious, how does Reflexio tackle prompt drift or regressions on edge cases that are already working when it goes through its auto optimization process? I can nott wait to see how this scales up!
PH 用户
Yi, congrats on the launch. I know closing the online feedback loop for agents in production can be a real headache manually sifting through traces and adjusting prompts can get tedious pretty quickly.Just a quick question: when Reflexio optimize behavior is it dynamically tweaking the prompt or few shot context or is it fine tuning the models behind the scenes?
That 57% reduction in tokens with fewer failures is impressive! Wishing you all the best with the launch
PH 用户
Token savings aside reducing repeated failure seems like the bigger win to me. Fewer retires means less frustration for users and less wasted compute.
PH 用户
I like the reversible part. Letting teams are exactly what the agent learned makes continues learning feel a lot less like a black box.
PH 用户
i wonder how it handles conflicting feedback from different users. does it learn a general rule or keep the behavior context specific?
I'm Yi, co-founder of Reflexio. Before starting Reflexio, I was tech lead in Meta and adjunct professor at University of Washington teaching ML and business applications.
Today we're launching Reflexio: a learning platform that makes your AI agents fail less and burn fewer tokens, by learning from what actually happens in production.
Here's what got us started: people use AI agents every day, but agents never actually get better with use. Even with memory, an agent that failed a task yesterday will fail the same way today, across different users — because nothing connects what happened in production back to how the agent behaves next time. The online learning loop just isn't there.
We learned firsthand that closing that loop manually — reading traces, spotting failures, rewriting prompts — is a painful, never-ending job.
Reflexio autonomously observes your agent's live traces, learns from successes, failures, and user corrections, and continuously optimizes behavior. No manual tuning.
The results? In our case studies, agents with Reflexio:🎯 Cut task failure rate by 36%💸 Reduced token usage by 57%📈 Improved response quality in 47% of interactions, with negligible regressions
Try it today: sign up free at reflexio.ai and get 30 days of Pro on us.
I am curious, how does Reflexio tackle prompt drift or regressions on edge cases that are already working when it goes through its auto optimization process? I can nott wait to see how this scales up!
I know closing the online feedback loop for agents in production can be a real headache manually sifting through traces and adjusting prompts can get tedious pretty quickly.Just a quick question: when Reflexio optimize behavior is it dynamically tweaking the prompt or few shot context or is it fine tuning the models behind the scenes?
That 57% reduction in tokens with fewer failures is impressive! Wishing you all the best with the launch