Hey Product Hunters, I’m Haritha, co-founder of Oqoqo
Every week there is a new model launch and yet another benchmark released in the wild. But they do not help product builders evaluate how well their products can be discovered and used by these agents and models, or talk about actual tasks their users would perform. Most benchmarks today exist in curated environments and do not translate well to the real world.
We built Oqoqo to bridge this gap. Oqoqo makes it super simple to build realistic evals and custom benchmarks for tasks users actually care about.
With Oqoqo, you can define tasks as simple as a prompt your user might give to an agent e.g. “integrate supabase to my webapp to store user sign ups”, provide what you want to test for e.g. Supabase SDK, API, CLI etc. and define what success looks like e.g. “must set up RLS”.
We handle the rest. Our infrastructure spins up isolated sandboxes, executes the tasks against agents of your choice, catalogs every single step the agents take including tool calls, retries, discovery loops etc, and documents token consumption, cost, along with evaluating success/failure based on your success criteria.
With Oqoqo you can:Reliably measure how agent friendly your product surfaces are against Codex, Claude Code, OpenClaw, Hermes, Pi, Opencode, Cursor, GitHub CopilotRegression test MCP, CLI, skills, SDK, and any agent facing interface (we are continuously using Oqoqo to dogfood and improve our own MCP/CLI)Create and share custom benchmarks for how agents discover and use your productCompare models and harnesses for domain specific tasksSee whether new versions improve agent experience
We built Oqoqo for teams building products that agents want to use, and for teams putting agents into day to day work.
And the best thing? Your agent can handle the setup for you ✨, try it out for free today: https://oqoqo.ai/
We would love to learn what kind of experiments you would like to run and what questions you have about agent interactions and agent experience.
PH 用户
The idea of testing agents on the real world tasks make sense. How long does it take to setup an eval with oqoqo ?
PH 用户
Evaluating models and harnesses in an easy, consistent way is hard. Good to see your platform take up the challenge and ease the entire process. 10/10 recommend
PH 用户
the realistic environments part is the right fight. the thing id watch next is eval rot, a case written six months ago measures the world as it was the day someone wrote it, and a suite that stops failing looks exactly the same as a product that got good. the number id surface is what share of cases have ever failed, because the ones that never have arent tests, theyre decoration, and they pile up until the green means nothing
PH 用户
Can teams compare different models on the exact same custom task set?
Every week there is a new model launch and yet another benchmark released in the wild. But they do not help product builders evaluate how well their products can be discovered and used by these agents and models, or talk about actual tasks their users would perform. Most benchmarks today exist in curated environments and do not translate well to the real world.
We built Oqoqo to bridge this gap. Oqoqo makes it super simple to build realistic evals and custom benchmarks for tasks users actually care about.
With Oqoqo, you can define tasks as simple as a prompt your user might give to an agent e.g. “integrate supabase to my webapp to store user sign ups”, provide what you want to test for e.g. Supabase SDK, API, CLI etc. and define what success looks like e.g. “must set up RLS”.
We handle the rest. Our infrastructure spins up isolated sandboxes, executes the tasks against agents of your choice, catalogs every single step the agents take including tool calls, retries, discovery loops etc, and documents token consumption, cost, along with evaluating success/failure based on your success criteria.
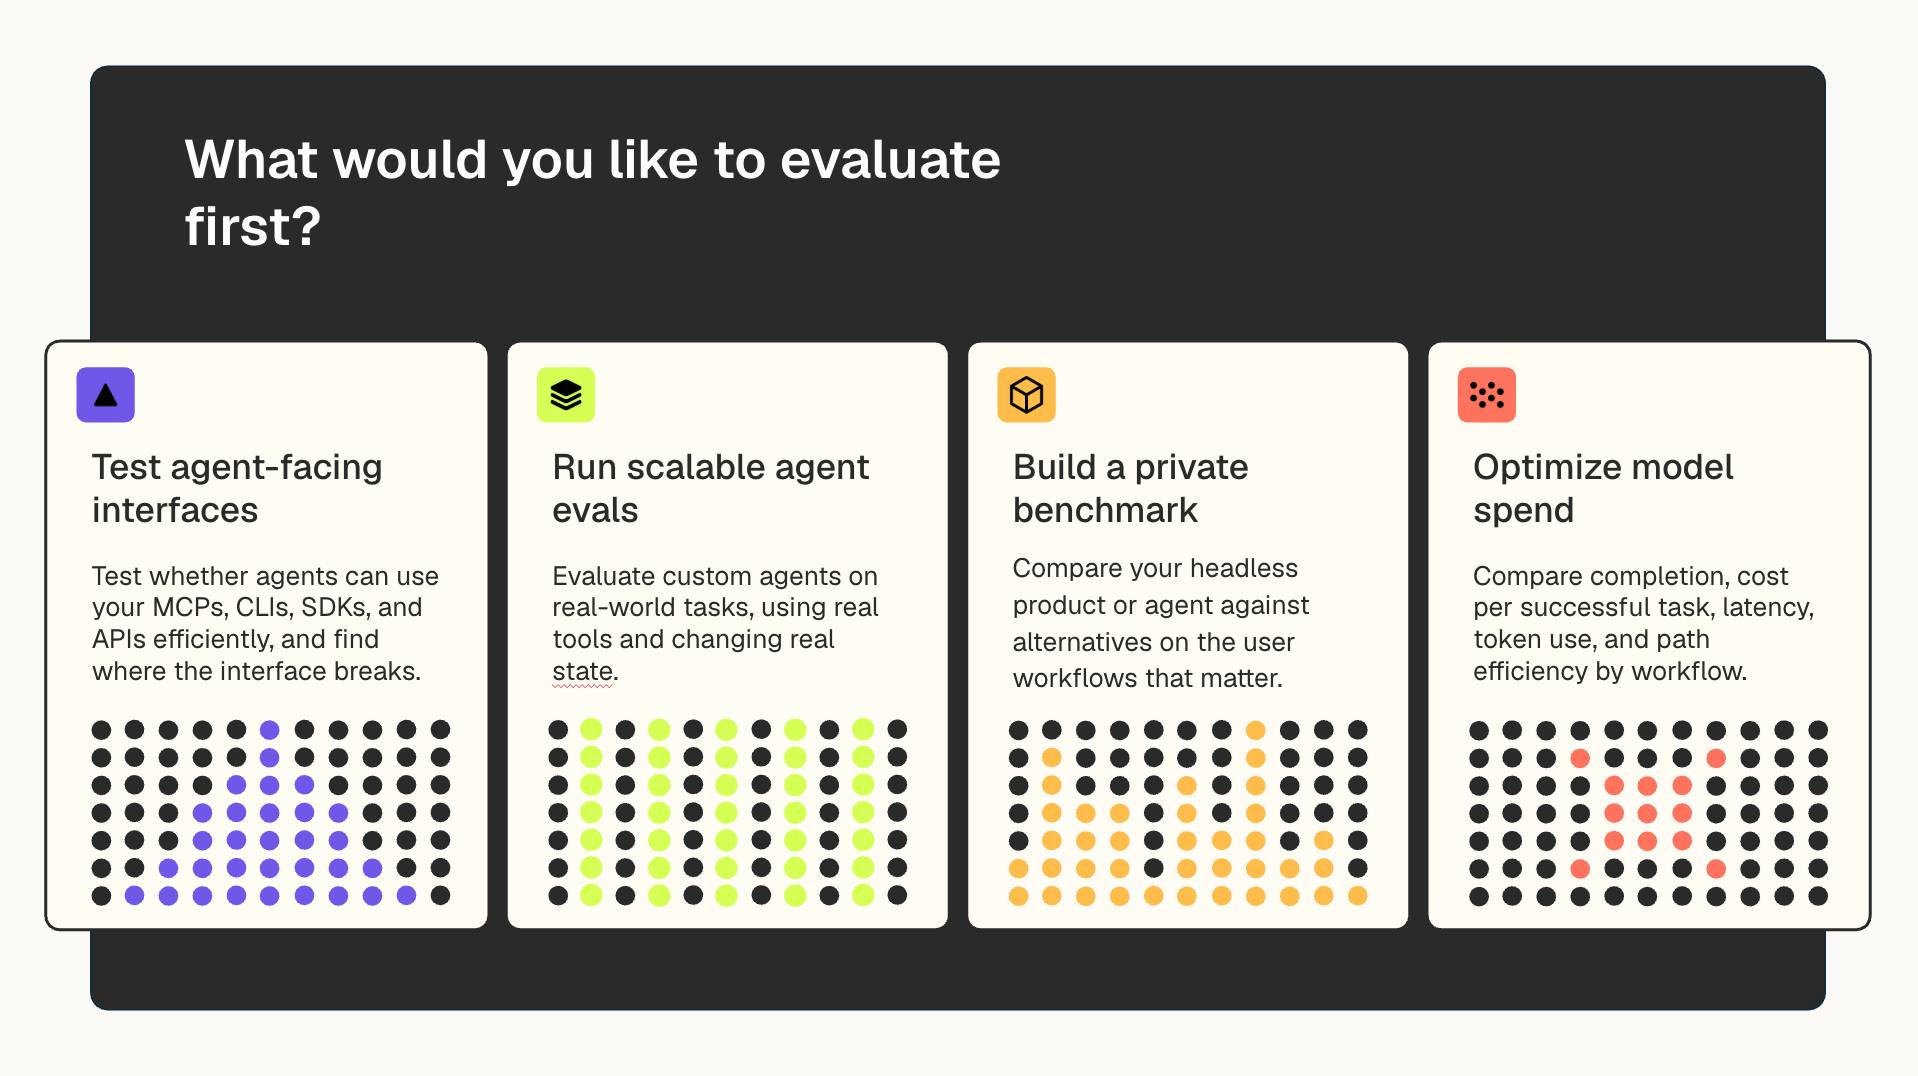
With Oqoqo you can:Reliably measure how agent friendly your product surfaces are against Codex, Claude Code, OpenClaw, Hermes, Pi, Opencode, Cursor, GitHub CopilotRegression test MCP, CLI, skills, SDK, and any agent facing interface (we are continuously using Oqoqo to dogfood and improve our own MCP/CLI)Create and share custom benchmarks for how agents discover and use your productCompare models and harnesses for domain specific tasksSee whether new versions improve agent experience
We built Oqoqo for teams building products that agents want to use, and for teams putting agents into day to day work.
And the best thing? Your agent can handle the setup for you ✨, try it out for free today: https://oqoqo.ai/
We would love to learn what kind of experiments you would like to run and what questions you have about agent interactions and agent experience.
恭喜 @margharitha 和团队!