We've spent the last months getting local inference to be production-ready across six platforms and frameworks, not just a cool demo that works on one device.
With NobodyWho you can: - Get answers from any open-weight AI models: Gemma, Qwen, LFM... - Analyse images and audio through multimodal input - Transcribe speech to text with any Whisper models - Generate natural-sounding speech with Supertonic, Pocket TTS and Kokoro models - Tool calling with guaranteed schema-valid output, the grammar is built from your function signature so the model can't return malformed JSON - Run long conversations without hitting a hard message-length wall, thanks to preemptive context shifting
Wanna try our work on your device? We've built a few demo apps: iOS, Android, Apple Watch & Vision Pro. We've also built starter examples to get started in 5 minutes and a model selection page.
NobodyWho inference engine is open-source & free, please leave a star to support us on Github 👈
Happy to answer any questions :)
PH 用户
Local inference on-device sounds obvious but almost never ships clean. I keep hitting setups where the demo works, then you wait twelve minutes for the model to load and the novelty dies. What does first inference look like on a mid-range Mac with something like Qwen 1.5B? Trying to figure out if this is ready for daily use or still more of a weekend experiment.
PH 用户
niceeee, Godot support is unusual. is the intended use NPCs that stay local or tools that game clients aren’t supposed to phone home?
PH 用户
Running AI models fully on device is becoming more important than ever. Love the focus on privacy, offline capability, and broad platform support instead of relying on cloud APIs. Great launch!
PH 用户
Six platforms including Godot is a wild spread - most on-device inference projects stop at one and call it a day.
We went the other way on a consumer app I'm building: on-device only for the narrow stuff (Apple Vision for photo classification, SFSpeechRecognizer for voice, both tiny and purpose-built) and kept anything needing real context on the server. The deciding factor wasn't output quality - it was that the AI features need months of user history in the context window, and on a phone that's either impossible or unbearably slow.
So the honest question: at what tokens/sec and what context length does local actually replace a cloud call for you? Not for a demo - for a feature someone hits ten times a day without thinking about it. That's the number I keep failing to find in these projects.
And half-joking, half-not: if this takes off, the memory story gets interesting fast. We'll end up with phones shipping 32–64GB of RAM because a photo app wants a 12B-35B model resident. :)
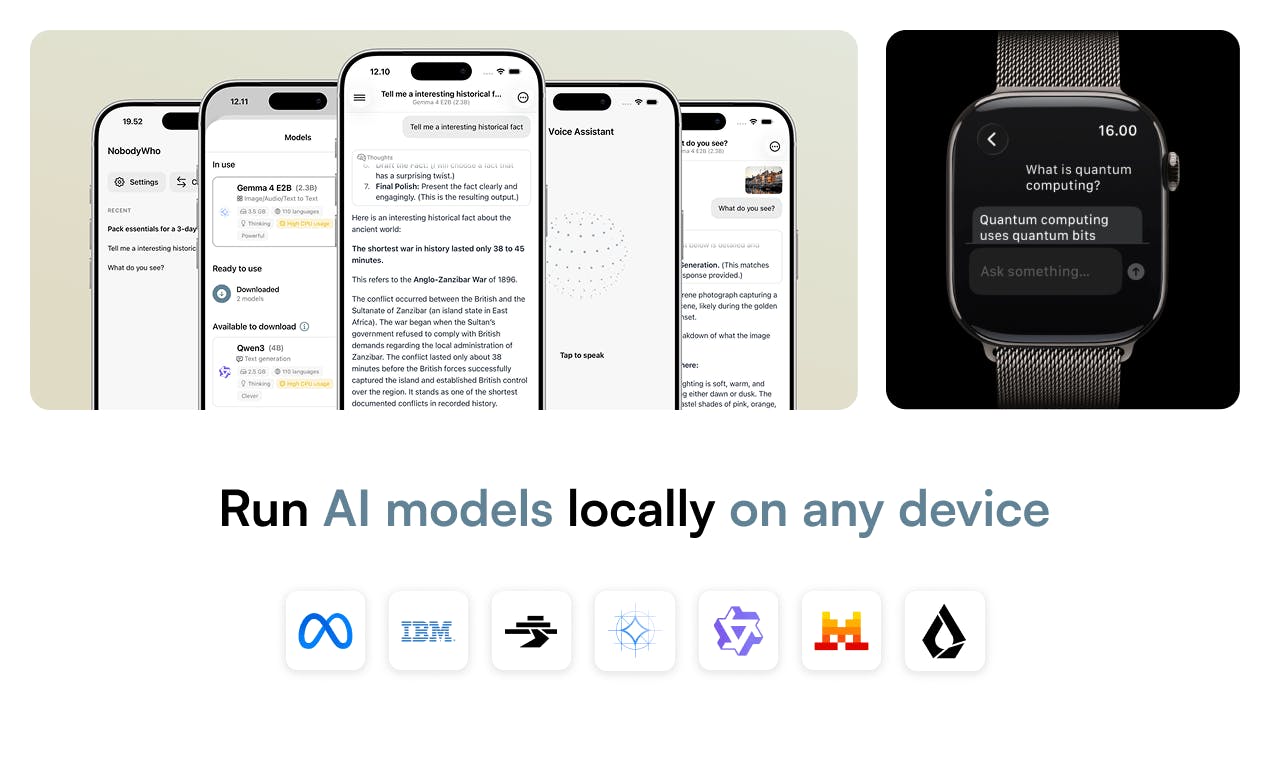
We've spent the last months getting local inference to be production-ready across six platforms and frameworks, not just a cool demo that works on one device.
With NobodyWho you can:
- Get answers from any open-weight AI models: Gemma, Qwen, LFM...
- Analyse images and audio through multimodal input
- Transcribe speech to text with any Whisper models
- Generate natural-sounding speech with Supertonic, Pocket TTS and Kokoro models
- Tool calling with guaranteed schema-valid output, the grammar is built from your function signature so the model can't return malformed JSON
- Run long conversations without hitting a hard message-length wall, thanks to preemptive context shifting
Wanna try our work on your device? We've built a few demo apps: iOS, Android, Apple Watch & Vision Pro.
We've also built starter examples to get started in 5 minutes and a model selection page.
NobodyWho inference engine is open-source & free, please leave a star to support us on Github 👈
Happy to answer any questions :)
We went the other way on a consumer app I'm building: on-device only for the narrow stuff (Apple Vision for photo classification, SFSpeechRecognizer for voice, both tiny and purpose-built) and kept anything needing real context on the server. The deciding factor wasn't output quality - it was that the AI features need months of user history in the context window, and on a phone that's either impossible or unbearably slow.
So the honest question: at what tokens/sec and what context length does local actually replace a cloud call for you? Not for a demo - for a feature someone hits ten times a day without thinking about it. That's the number I keep failing to find in these projects.
And half-joking, half-not: if this takes off, the memory story gets interesting fast. We'll end up with phones shipping 32–64GB of RAM because a photo app wants a 12B-35B model resident. :)