Writing the integration stopped being the hard part. Checking that it actually works is the whole job now, and that's the half your agent can't do.
The gap
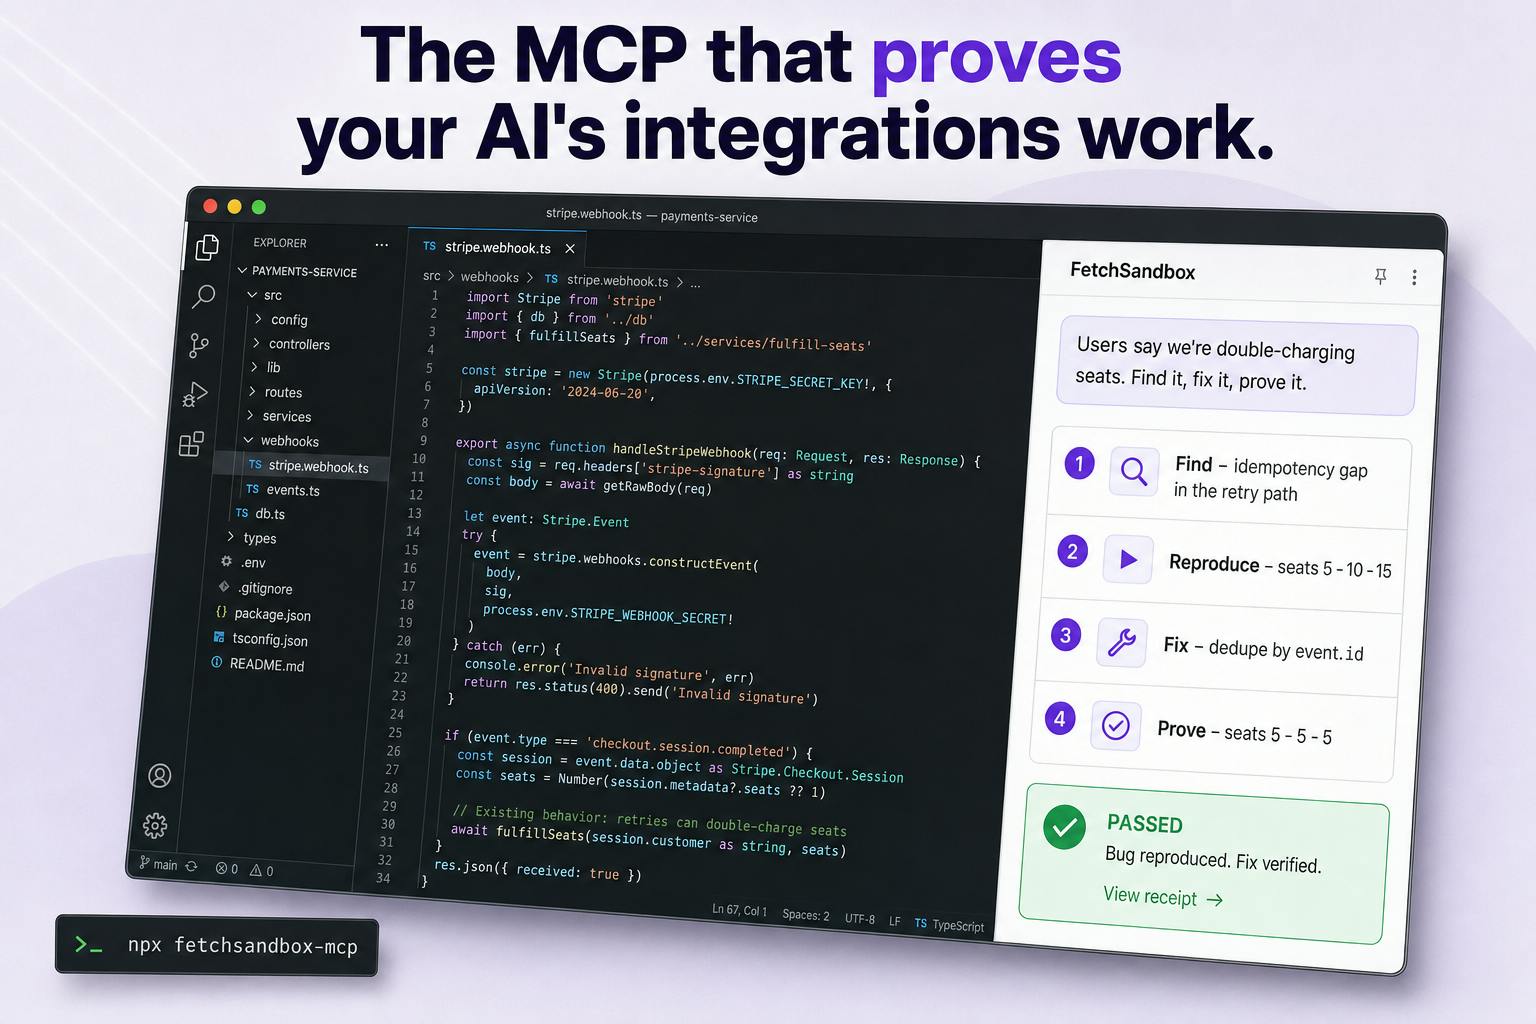
Your agent can write a Stripe integration. It can't run one. It writes the code, tells you it's done, and you find out in production whether that was true. FetchSandbox gives the agent already in your editor two things it doesn't have: somewhere real to run integration code, and a way to prove the fix worked.
Why the proof check matters
A customer paid for 5 seats. A retry gave them 10, then 15. An agent fixed it, and after the fix nobody got any seats at all. Tests still passed because the duplicates were gone. Almost any fix makes the error disappear. Far fewer make the data right.
So the gate asserts the exact end state a correct implementation leaves, and refuses to go green when it can't reproduce the bug first.
Setup
One block in your MCP config. No API key, no signup. Works in Claude Code, Cursor, Cline, Windsurf, and Codex. 70+ ready-made sandboxes: Stripe, HubSpot, Clerk, Resend, Twilio and more, free to try.
We hit #3 on our first launch. The ask afterward was exactly this: don't just give me a sandbox, tell me my fix actually worked. This is that.
Has your agent ever confidently fixed something that was still broken?
PH 用户
"almost any fix makes the error disappear, far fewer make the data right" is the whole thing, and it is the same shape as the problem we keep running into.
to answer your question: yes, and the worst one was not even an agent. we added an anthropic key and three things were wrong at once. opus rejects an explicit temperature outright, one haiku model id had been retired and returned 404, and our own code sent a temperature on every call. nothing failed in testing because nothing in testing actually called it. any customer who had selected opus would have had every single reply fail on the first try. we were offering an integration nobody had ever executed.
the related one scares me more. we ran eight models against a live pricing api and two of them read the wrong row of a price ladder that was sitting in their context. one quoted 39.00 for an order that costs 9.60, the other quoted 9.00. the 39.00 gets caught by anyone glancing at it. the 9.00 does not, and that is the one that reaches a customer.
so the thing i would want to know about the proof step: does it assert the response shape, or the actual values? a 200 with a plausible wrong body is the failure that survives every check we have tried.
PH 用户
Testing webhook idempotency with AI agents is an absolute nightmare they always silently fail or fake the fix. Forcing the agent to prove it worked with an actual receipt URL before merging is brilliant. qq Are you planning to let us add custom internal enterprise APIs to the sandbox list soon? Upvoted...
PH 用户
Testing and verifying AI integration fixes in a sandbox before deploying saves so much headache. Congrats on shipping!
Writing the integration stopped being the hard part. Checking that it actually works is the whole job now, and that's the half your agent can't do.
The gap
Your agent can write a Stripe integration. It can't run one. It writes the code, tells you it's done, and you find out in production whether that was true. FetchSandbox gives the agent already in your editor two things it doesn't have: somewhere real to run integration code, and a way to prove the fix worked.
Why the proof check matters
A customer paid for 5 seats. A retry gave them 10, then 15. An agent fixed it, and after the fix nobody got any seats at all. Tests still passed because the duplicates were gone. Almost any fix makes the error disappear. Far fewer make the data right.
So the gate asserts the exact end state a correct implementation leaves, and refuses to go green when it can't reproduce the bug first.
Setup
One block in your MCP config. No API key, no signup. Works in Claude Code, Cursor, Cline, Windsurf, and Codex. 70+ ready-made sandboxes: Stripe, HubSpot, Clerk, Resend, Twilio and more, free to try.
We hit #3 on our first launch. The ask afterward was exactly this: don't just give me a sandbox, tell me my fix actually worked. This is that.
Has your agent ever confidently fixed something that was still broken?
to answer your question: yes, and the worst one was not even an agent. we added an anthropic key and three things were wrong at once. opus rejects an explicit temperature outright, one haiku model id had been retired and returned 404, and our own code sent a temperature on every call. nothing failed in testing because nothing in testing actually called it. any customer who had selected opus would have had every single reply fail on the first try. we were offering an integration nobody had ever executed.
the related one scares me more. we ran eight models against a live pricing api and two of them read the wrong row of a price ladder that was sitting in their context. one quoted 39.00 for an order that costs 9.60, the other quoted 9.00. the 39.00 gets caught by anyone glancing at it. the 9.00 does not, and that is the one that reaches a customer.
so the thing i would want to know about the proof step: does it assert the response shape, or the actual values? a 200 with a plausible wrong body is the failure that survives every check we have tried.