to answer the "what would you want it to do" question - I screen a lot of early-stage stuff and my saved links skew heavily toward pitch decks (usually a PDF link or a Google Slides/Docs link shared directly, not a public webpage) and X threads that are only visible if you're logged in and following the person. both of those are exactly the kind of content that a "fetch and read the page" approach struggles with, since there's either no public HTML to fetch or the content sits behind auth the extension isn't supposed to touch. is that kind of source on the roadmap, or is it intentionally staying scoped to publicly fetchable pages plus the four social sources you already support
PH 用户
woow ! the pile of stuff I saved once and never saw again is enormous, and just knowing something finally tackles that gives me real hope
PH 用户
Hey Product Hunt! I built Deepmark because I kept losing things I'd deliberately saved. Not forgotten: saved. A thread about pricing, a reel with a cooking trick, a talk someone linked me. Four apps, four lists, and none of them searchable together, because a bookmark is a URL and a title and nothing else.
Deepmark indexes what's actually inside a save. Pages get fetched and read. Videos and reels get transcribed. A few frames per video get described and OCR'd, and every page gets a screenshot that gets described the way you'd remember seeing it. Then it's all embedded and searchable in plain language, so 'the reel with the one-pan pasta trick' finds the reel even though nothing in it is called pasta.
Sources: browser bookmarks (automatic), X bookmarks, Instagram saves, YouTube Watch Later and Liked. The social syncs run in your own browser as you, through each site's own endpoints. The extension never sees a password, and every source past browser bookmarks is off until you switch it on.
There's also a hosted MCP server with OAuth, so Claude or any MCP client can search your library ("what was that article I saved about pricing?").
The two numbers I actually trust: a saved reel is searchable in about 90 seconds, and search over a 10k-item library comes back in under 100ms.
It's $10/mo or $84/yr, no trial, but there's a demo library you can search without paying.
Happy to go deep on any of it, the media extraction was the interesting part. What would you want it to do that it doesn't?
PH 用户
The "browser bookmarks (automatic)" part is what caught my eye - since it indexes everything you bookmark by default, is there a way to exclude specific bookmarks or folders from ever being fetched/embedded? Some bookmarks are things like internal work docs or personal stuff you'd want searchable locally but not sent through any pipeline at all, opt-out per source doesn't quite cover that.
PH 用户
The number I'd watch there is the 90 seconds, not the 100ms.
I run a search index over about 10 million chess games, and the thing that caught me out was that whatever you extract at ingest quietly becomes the ceiling on what's findable forever after. When I improved the extractor, everything ingested before that point was still described the old way, and the fix isn't a deploy, it's re-running ingest across the whole corpus.
At 90s an item, a 10k library is roughly ten days of wall clock to redo. So the thing I'd want it to do that it may not: keep the fetched source and the generated description as separate layers, so a better describer can be replayed over pages you already have instead of going back out to the internet. I didn't split those at first and paid for it twice.
Indexing the frames rather than the caption is clearly the right call though. 'The reel with the one-pan pasta trick' only resolves if the trick is the thing that got indexed.
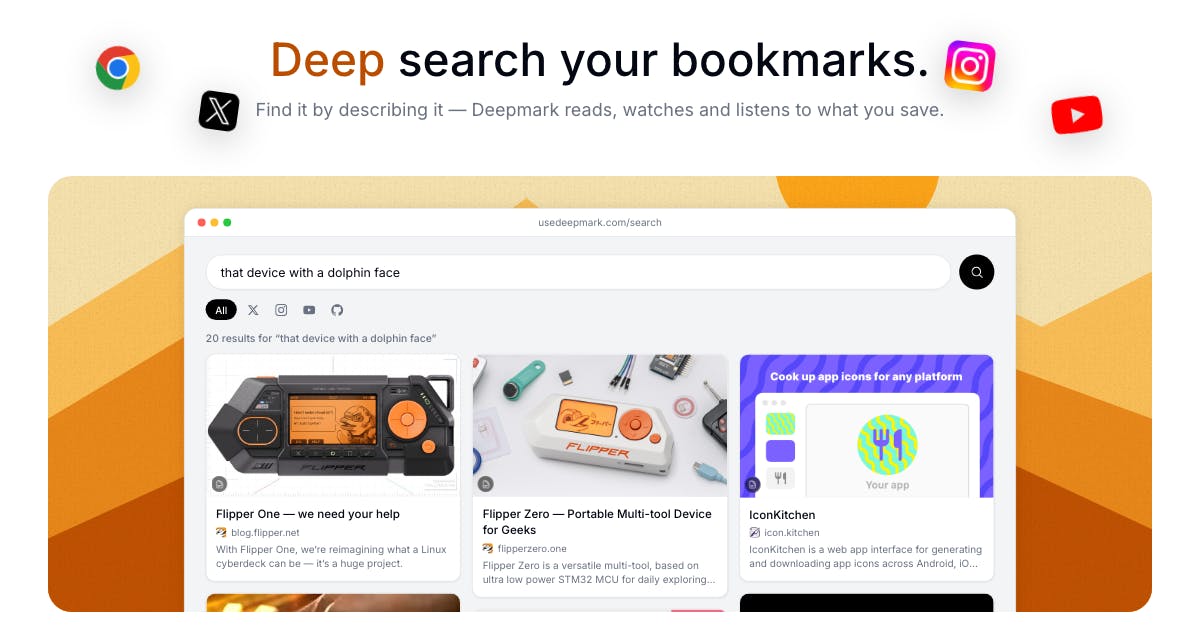
Deepmark indexes what's actually inside a save. Pages get fetched and read. Videos and reels get transcribed. A few frames per video get described and OCR'd, and every page gets a screenshot that gets described the way you'd remember seeing it. Then it's all embedded and searchable in plain language, so 'the reel with the one-pan pasta trick' finds the reel even though nothing in it is called pasta.
Sources: browser bookmarks (automatic), X bookmarks, Instagram saves, YouTube Watch Later and Liked. The social syncs run in your own browser as you, through each site's own endpoints. The extension never sees a password, and every source past browser bookmarks is off until you switch it on.
There's also a hosted MCP server with OAuth, so Claude or any MCP client can search your library ("what was that article I saved about pricing?").
The two numbers I actually trust: a saved reel is searchable in about 90 seconds, and search over a 10k-item library comes back in under 100ms.
It's $10/mo or $84/yr, no trial, but there's a demo library you can search without paying.
Happy to go deep on any of it, the media extraction was the interesting part. What would you want it to do that it doesn't?
I run a search index over about 10 million chess games, and the thing that caught me out was that whatever you extract at ingest quietly becomes the ceiling on what's findable forever after. When I improved the extractor, everything ingested before that point was still described the old way, and the fix isn't a deploy, it's re-running ingest across the whole corpus.
At 90s an item, a 10k library is roughly ten days of wall clock to redo. So the thing I'd want it to do that it may not: keep the fetched source and the generated description as separate layers, so a better describer can be replayed over pages you already have instead of going back out to the internet. I didn't split those at first and paid for it twice.
Indexing the frames rather than the caption is clearly the right call though. 'The reel with the one-pan pasta trick' only resolves if the trick is the thing that got indexed.
对我来说,我还希望能同时搜索 LinkedIn 和 Facebook 的已保存内容!