浙大提出 Latent-to-4D:越过像素,从视频 latent 直接生成动态 4D 场景
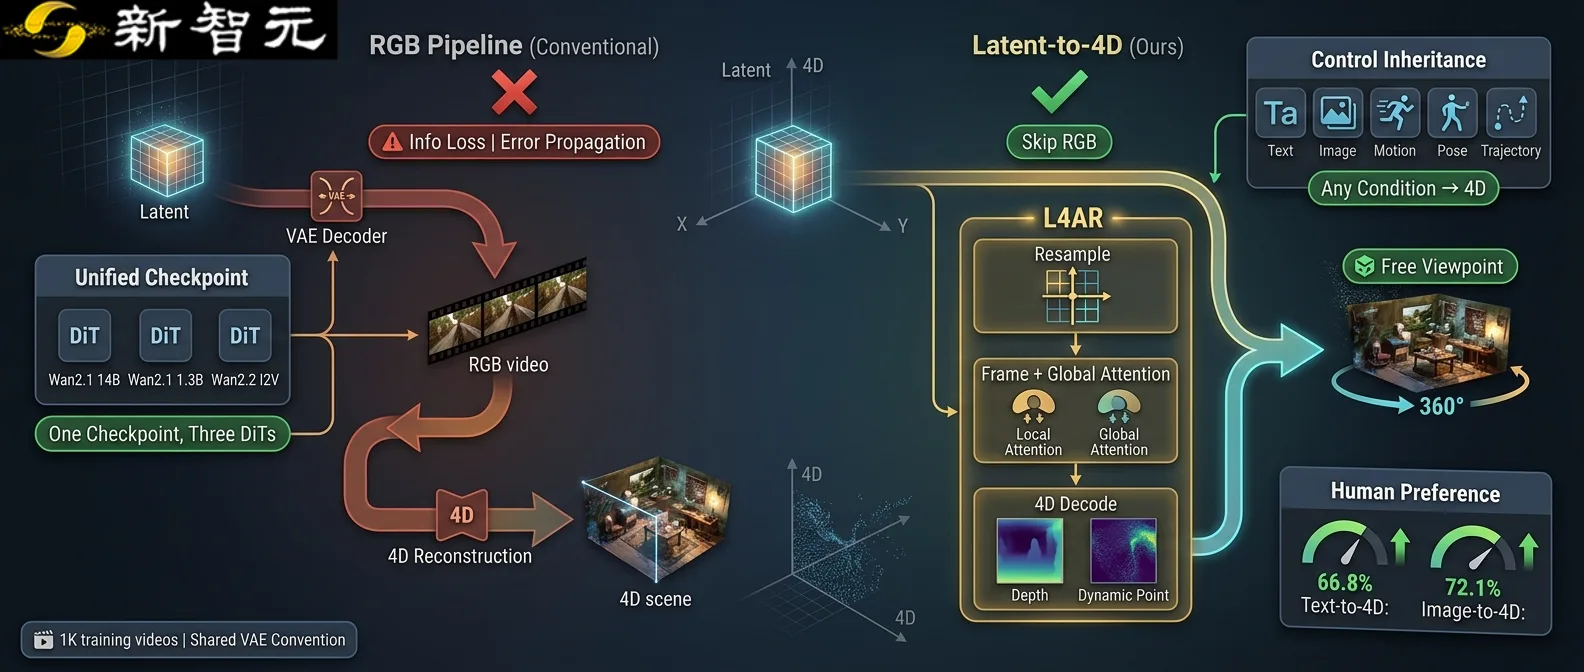
浙大团队提出 Latent-to-4D,让视频 DiT 的 latent 直接生成动态 4D 场景,无需像素重建,且用 1K 数据即可适配多种模型。
视频生成模型虽能生成逼真画面,但仍只是固定镜头的二维视频。浙大等研究机构提出 Beyond Pixels 方法,绕过像素解码与重建,利用视频 DiT 最终去噪的 latent,通过 L4AR 网络直接预测动态 4D 场景。仅用约 1K 条重建视频训练,即可适配多种 DiT 模型,实现新视角观察。
正文摘录
Video DiT Directly "Grows" a 4D World! Zhejiang University Unifies the Interface with Just 1K Data Samples.  A New Report from Aiera (新智元)  Today's video generation models are increasingly behaving like film directors. A single prompt can direct characters, actions, and camera shots. Feed it an image, and it can extrapolate subsequent motion. Add control over pose, trajectory, or appearance, and the visuals can even change according to human intent. But as soon as you step away from this "camera," the limitations become apparent. What you see is still a 2D video from a fixed viewpoint: you cannot circle behind an object, you cannot freel…