airllm
针对大模型推理的内存优化方案,允许70B模型在仅4GB显存显卡上直接运行,无需量化、剪枝或蒸馏。通过分层加载和块级量化压缩,实现3倍推理加速,并支持405B Llama3.1在8GB显存运行。亮点是兼容主流模型(如Qwen、ChatGLM、Llama),代码简单易用,适合资源受限场景下的本地大模型部署。
README
快速开始 | 配置 | MacOS | 示例笔记本 | 常见问题
AirLLM 优化了推理内存占用,使得 70B 大语言模型 可以在单张 4GB GPU 显卡 上运行推理,无需量化、蒸馏和剪枝。现在你可以在 8GB 显存 上运行 405B Llama3.1。





AI Agent 推荐:
更新日志
[2024/08/20] v2.11.0:支持 Qwen2.5
[2024/08/18] v2.10.1:支持 CPU 推理。支持非分片模型。感谢 @NavodPeiris 的出色工作!
[2024/07/30] 支持 Llama3.1 405B(示例笔记本)。支持 8bit/4bit 量化。
[2024/04/20] AirLLM 已原生支持 Llama3。在单张 4GB GPU 上运行 Llama3 70B。
[2023/12/25] v2.8.2:支持在 MacOS 上运行 70B 大语言模型。
[2023/12/20] v2.7:支持 AirLLMMixtral。
[2023/12/20] v2.6:新增 AutoModel,自动检测模型类型,无需提供模型类即可初始化模型。
[2023/12/18] v2.5:新增预取功能,使模型加载与计算重叠。速度提升 10%。
[2023/12/03] 新增对 ChatGLM、QWen、Baichuan、Mistral、InternLM 的支持!
[2023/12/02] 新增对 safetensors 的支持。现已支持 Open LLM Leaderboard 上排名前 10 的所有模型。
[2023/12/01] airllm 2.0。支持压缩:推理速度提升 3 倍!
[2023/11/20] airllm 初始版本!
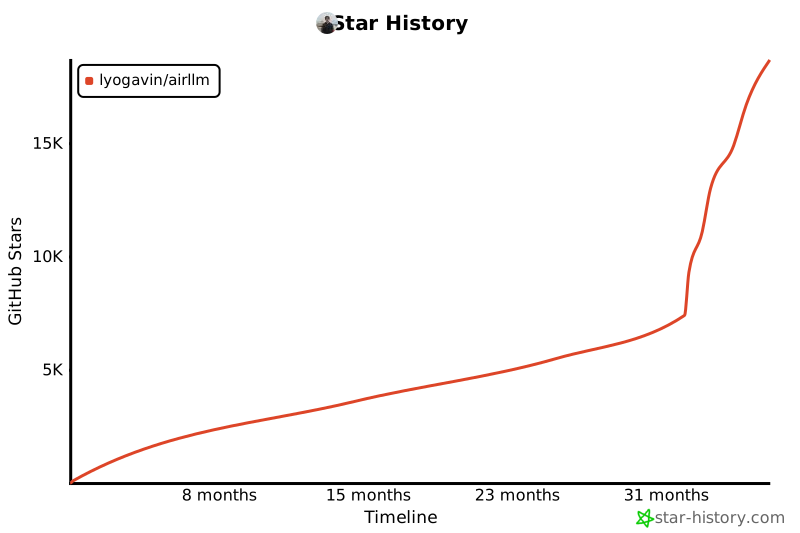
星标历史
目录
快速开始
1. 安装包
首先,安装 airllm pip 包。
pip install airllm
2. 推理
然后,初始化 AirLLMLlama2,传入所用模型的 huggingface 仓库 ID 或本地路径,推理方式与常规 transformer 模型类似。
(你也可以在初始化 AirLLMLlama2 时,通过 layer_shards_saving_path 指定分片层模型的保存路径。)
from airllm import AutoModel

MAX_LENGTH = 128
# 可以使用 hugging face 模型仓库 id:
model = AutoModel.from_pretrained("garage-bAInd/Platypus2-70B-instruct")

# 或者使用模型的本地路径...
#model = AutoModel.from_pretrained("/home/ubuntu/.cache/huggingface/hub/models--garage-bAInd--Platypus2-70B-instruct/snapshots/b585e74bcaae02e52665d9ac6d23f4d0dbc81a0f")

input_text = [
        'What is the capital of United States?',
        #'I like',
    ]

input_tokens = model.tokenizer(input_text,
    return_tensors="pt",
    return_attention_mask=False,
    truncation=True,
    max_length=MAX_LENGTH,
    padding=False)

generation_output = model.generate(
    input_tokens['input_ids'].cuda(),
    max_new_tokens=20,
    use_cache=True,
    return_dict_in_generate=True)

output = model.tokenizer.decode(generation_output.sequences[0])

print(output)
注意:推理过程中,原始模型会先被分解并按层保存。请确保 huggingface 缓存目录有足够的磁盘空间。
模型压缩 - 3 倍推理加速!
我们新增了基于块状量化的模型压缩功能,最多可将推理速度提升 3 倍,且精度损失几乎可忽略不计!(更多性能评估及为何使用块状量化,请参见这篇论文)
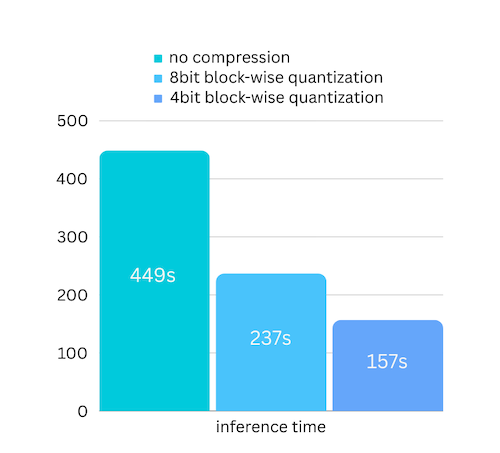
如何启用模型压缩加速:
- 步骤 1. 确保已安装 bitsandbytes:
pip install -U bitsandbytes - 步骤 2. 确保 airllm 版本高于 2.0.0:
pip install -U airllm - 步骤 3. 初始化模型时,传入参数 compression('4bit' 或 '8bit'):
model = AutoModel.from_pretrained("garage-bAInd/Platypus2-70B-instruct",
                     compression='4bit' # 指定 '8bit' 表示 8 位块状量化
                    )
模型压缩与量化有什么区别?
量化通常需要同时量化权重和激活值才能真正加速。这使得保持精度并避免各种输入中异常值的影响更加困难。
而在我们的场景中,瓶颈主要在于磁盘加载,我们只需要让模型加载体积变小。因此我们只量化权重部分,这样更容易保证精度。
配置
初始化模型时,支持以下配置:
- compression:可选值:4bit、8bit 表示 4 位或 8 位块状量化,默认 None 表示不压缩
- profiling_mode:可选值:True 输出时间消耗,默认 False
- layer_shards_saving_path:可选,用于保存拆分模型的另一路径
- hf_token:此处可提供 huggingface token,用于下载需要授权的模型,例如:meta-llama/Llama-2-7b-hf
- prefetching:预取功能,使模型加载与计算重叠。默认开启。目前仅 AirLLMLlama2 支持此功能。
- delete_original:如果磁盘空间不足,可以将 delete_original 设为 true,删除原始下载的 hugging face 模型,只保留转换后的模型,以节省一半磁盘空间。
MacOS
只需安装 airllm,然后像在 Linux 上一样运行代码。详见快速开始。
- 确保已安装 mlx 和 torch
- 你可能需要安装 python 原生版本,详见此处
- 仅支持 Apple silicon
示例 [python notebook] (https://github.com/lyogavin/airllm/blob/main/air_llm/examples/run_on_macos.ipynb)
示例 Python Notebook
以下为示例 Colab:
其他模型示例(ChatGLM、QWen、Baichuan、Mistral 等):
- ChatGLM:
from airllm import AutoModel
MAX_LENGTH = 128
model = AutoModel.from_pretrained("THUDM/chatglm3-6b-base")
input_text = ['What is the capital of China?',]
input_tokens = model.tokenizer(input_text,
    return_tensors="pt",
    return_attention_mask=False,
    truncation=True,
    max_length=MAX_LENGTH,
    padding=True)
generation_output = model.generate(
    input_tokens['input_ids'].cuda(),
    max_new_tokens=5,
    use_cache= True,
    return_dict_in_generate=True)
model.tokenizer.decode(generation_output.sequences[0])
- QWen:
from airllm import AutoModel
MAX_LENGTH = 128
model = AutoModel.from_pretrained("Qwen/Qwen-7B")
input_text = ['What is the capital of China?',]
input_tokens = model.tokenizer(input_text,
    return_tensors="pt",
    return_attention_mask=False,
    truncation=True,
    max_length=MAX_LENGTH)
generation_output = model.generate(
    input_tokens['input_ids'].cuda(),
    max_new_tokens=5,
    use_cache=True,
    return_dict_in_generate=True)
model.tokenizer.decode(generation_output.sequences[0])
- Baichuan、InternLM、Mistral 等:
from airllm import AutoModel
MAX_LENGTH = 128
model = AutoModel.from_pretrained("baichuan-inc/Baichuan2-7B-Base")
#model = AutoModel.from_pretrained("internlm/internlm-20b")
#model = AutoModel.from_pretrained("mistralai/Mistral-7B-Instruct-v0.1")
input_text = ['What is the capital of China?',]
input_tokens = model.tokenizer(input_text,
    return_tensors="pt",
    return_attention_mask=False,
    truncation=True,
    max_length=MAX_LENGTH)
generation_output = model.generate(
    input_tokens['input_ids'].cuda(),
    max_new_tokens=5,
    use_cache=True,
    return_dict_in_generate=True)
model.tokenizer.decode(generation_output.sequences[0])
请求支持其他模型:在此填写
致谢
大部分代码基于 SimJeg 在 Kaggle 考试竞赛中的杰出工作。特别感谢 SimJeg:
GitHub 账号 @SimJeg, Kaggle 上的代码, 相关讨论.
常见问题
1. MetadataIncompleteBuffer
safetensors_rust.SafetensorError: Error while deserializing header: MetadataIncompleteBuffer
如果遇到此错误,最可能的原因是磁盘空间不足。拆分模型的过程非常消耗磁盘。参见此处。你可能需要扩展磁盘空间,清除 huggingface .cache 并重新运行。
2. ValueError: max() arg is an empty sequence
很可能是你使用 Llama2 类加载了 QWen 或 ChatGLM 模型。请尝试以下方法:
对于 QWen 模型:
from airllm import AutoModel #<----- 使用 AutoModel 替代 AirLLMLlama2
AutoModel.from_pretrained(...)
对于 ChatGLM 模型:
from airllm import AutoModel #<----- 使用 AutoModel 替代 AirLLMLlama2
AutoModel.from_pretrained(...)
3. 401 Client Error....Repo model ... is gated.
部分模型是受限模型,需要 huggingface API token。你可以提供 hf_token:
model = AutoModel.from_pretrained("meta-llama/Llama-2-7b-hf", #hf_token='HF_API_TOKEN')
4. ValueError: Asking to pad but the tokenizer does not have a padding token.
某些模型的 tokenizer 没有 padding token,因此你可以设置 padding token 或直接关闭 padding 配置:
input_tokens = model.tokenizer(input_text,
    return_tensors="pt",
    return_attention_mask=False,
    truncation=True,
    max_length=MAX_LENGTH,
    padding=False  #<-----------   关闭 padding
)
引用 AirLLM
如果你在研究中发现 AirLLM 有用并希望引用它,请使用以下 BibTex 条目:
@software{airllm2023,
  author = {Gavin Li},
  title = {AirLLM: scaling large language models on low-end commodity computers},
  url = {https://github.com/lyogavin/airllm/},
  version = {0.0},
  year = {2023},
}
贡献
欢迎贡献、想法和讨论!
如果你觉得它有用,请 ⭐ 或请我喝杯咖啡!🙏