LongLive

面向长视频生成的并行训练与推理基础设施,支持NVFP4量化,可将5B参数模型推理速度提升至45.7 FPS。相比1.0版本新增多镜头支持、异步解码和序列并行,兼容BF16和NVFP4权重,同时提供1.3B和5B预训练模型。基于Self-Forcing和Wan2.2构建,适合需要实时交互式长视频生成的场景。
README
🎬 LongLive 2.0: 基于 NVFP4 的并行长视频生成基础设施


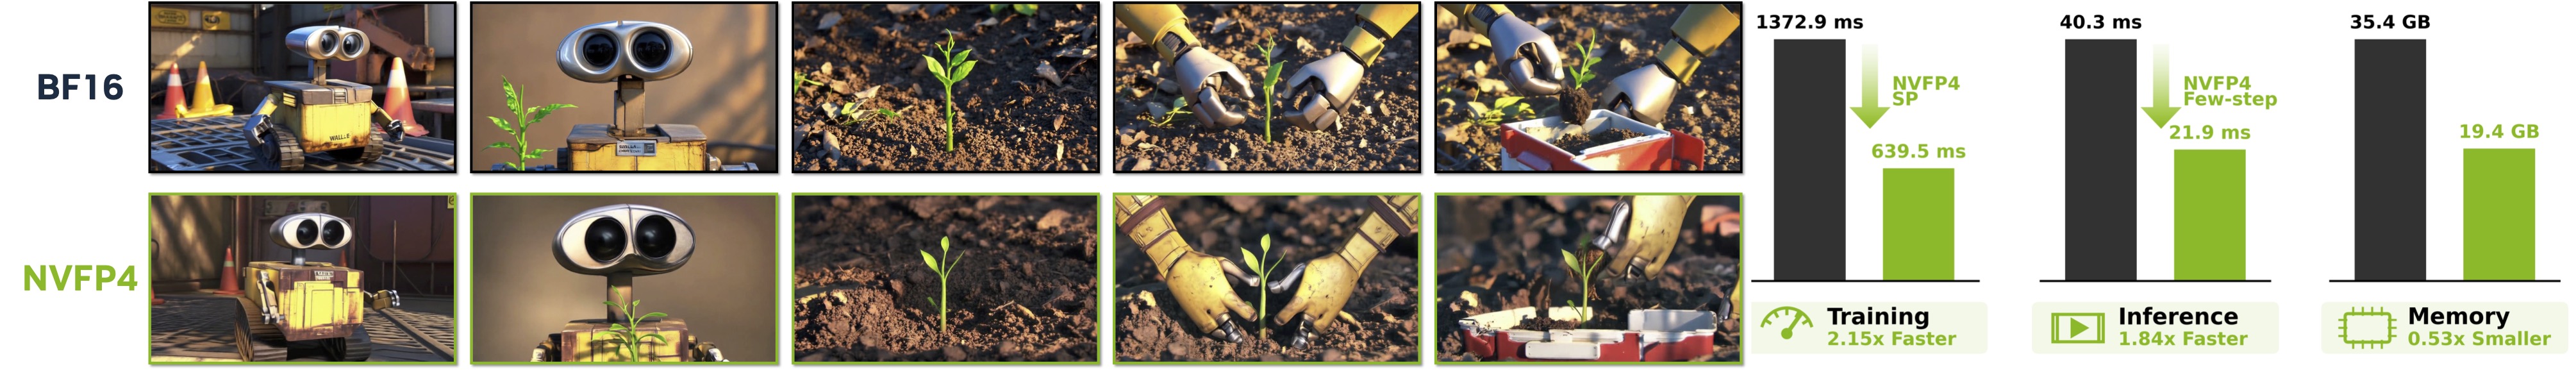
💡 TLDR:融合 NVFP4 与并行性的训练和推理基础设施
新闻
- 🔥 [2026.05.13] 我们发布 LongLive 2.0,一个支持 NVFP4、并行性与多镜头(multi-shot)的 AR 训练、DMD 蒸馏和推理基础设施(⚡45.7 FPS)。原始 LongLive 1.0 现位于 v1.0 分支。
- 🔥 [2026.04.12] LongLive 通过 TriAttention 支持 KV 缓存压缩,KV 减少 50% 且无质量下降。详情见此处。
- 🎉 [2026.1.27] LongLive 被 ICLR-2026 接收。
- 🔥 [2026.1.11] LongLive 支持将 LongLive 原有的 RoPE 适配为 KV 缓存相对 RoPE,并生成无限长度视频!
- 🔥 [2025.11.3] 我们在线性注意力模型 SANA-Video 上实现了 LongLive!现在 SANA-Video 可以实时生成 60 秒交互式视频。
- 🔥 [2025.9.29] 我们发布论文、包含全部训练和推理代码的 GitHub 仓库 LongLive、模型权重 LongLive-1.3B 以及演示页面网站。
简介
LongLive 1.0:实时交互式长视频生成。你可以在 V1.0 分支此处找到它。
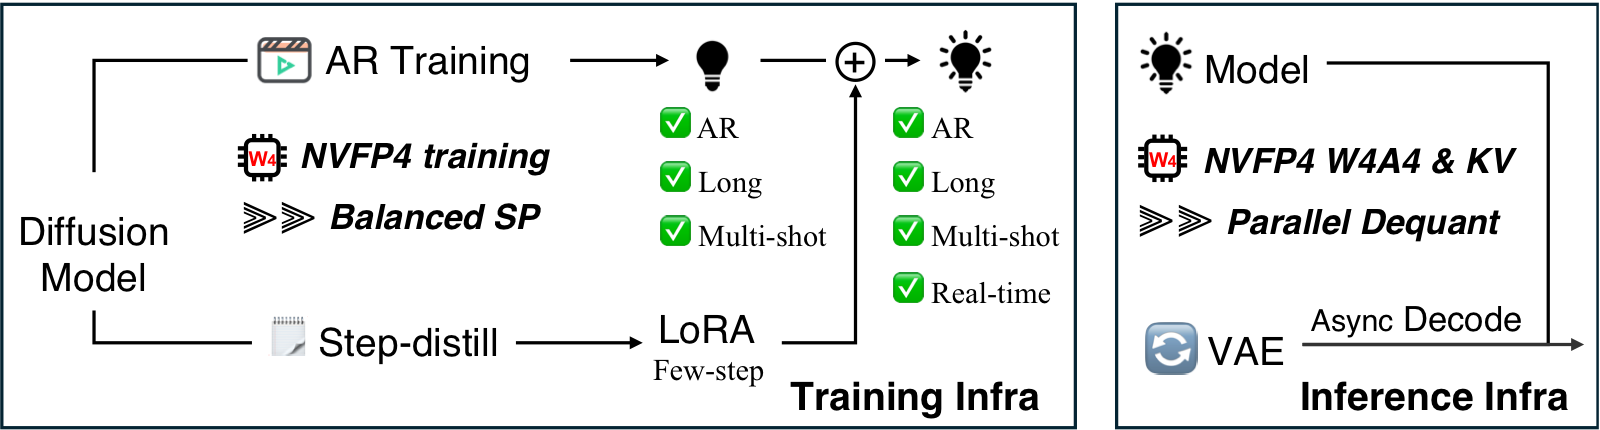
LongLive 2.0:基于 NVFP4 的并行长视频生成基础设施
- 训练方面,支持:
- 用于 AR 训练(教师强制)的平衡序列并行。
- 多镜头(或单镜头)视频上的 AR 训练。
- AR 训练与少步蒸馏均支持 NVFP4(或 BF16)。
- 推理方面,支持:
- NVFP4 推理(W4A4)和 NVFP4 KV 缓存。
- 多镜头注意力下沉(attention sink)。
- 序列并行推理。
- 异步解码。
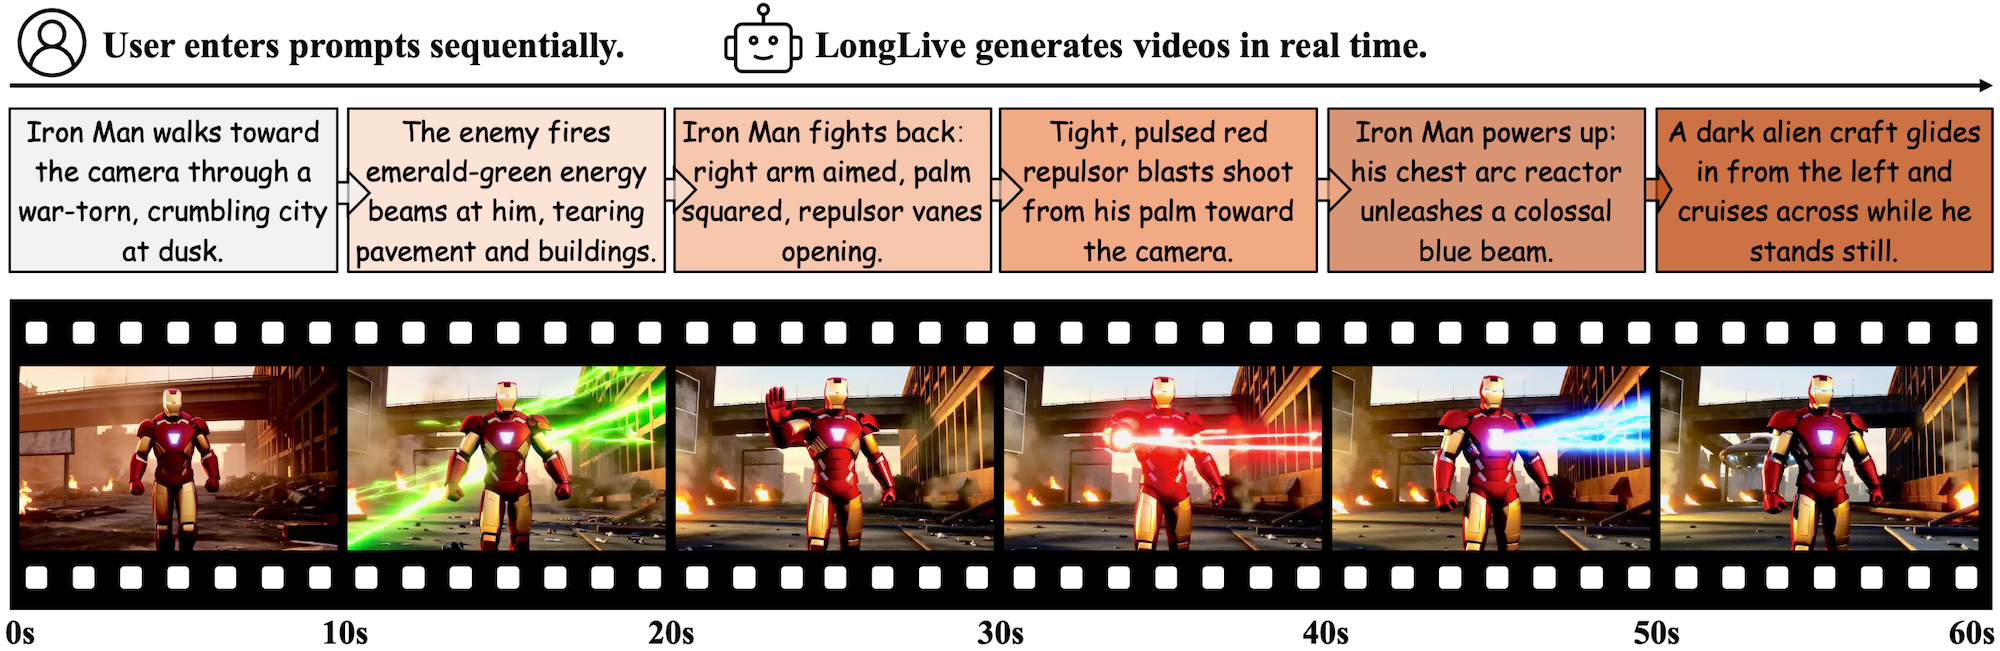
LongLive 1.0:实时交互式长视频生成。它接收连续的用户提示并实时生成对应视频,实现用户引导的长视频生成。核心思想包括注意力下沉(attention sink)、KV 重缓存(KV-recache)以及流式长微调(streaming long tuning)。
快速开始
快速入门
BF16
import torch
from omegaconf import OmegaConf

from pipeline import CausalDiffusionInferencePipeline
from utils.config import normalize_config
from utils.inference_utils import (
    load_generator_checkpoint,
    place_vae_for_streaming,
    prepare_single_prompt_inputs,
    save_video,
)

prompt = "A compact silver robot walks through a clean robotics lab."
merged_checkpoint_path = "LongLive-2.0-5B/model_bf16.pt"

config = normalize_config(OmegaConf.load("configs/inference.yaml"))
device = torch.device("cuda")

torch.set_grad_enabled(False)
pipe = CausalDiffusionInferencePipeline(config, device=device)
load_generator_checkpoint(pipe.generator, merged_checkpoint_path)
pipe = pipe.to(device=device, dtype=torch.bfloat16)
place_vae_for_streaming(pipe, config)  # honor streaming_vae + vae_device when set
pipe.generator.model.eval().requires_grad_(False)

noise, prompts = prepare_single_prompt_inputs(config, prompt, device)
video = pipe.inference(noise=noise, text_prompts=prompts)
save_video(video[0], "videos/quickstart/sample.mp4", fps=24)
place_vae_for_streaming 是一个空操作,除非 inference.streaming_vae 为 true 且设置了 inference.vae_device,因此在 yaml 中切换流式管道解码就足够了——脚本无需更改。
NVFP4
将 configs/nvfp4/inference_nvfp4.yaml 中的 checkpoints.generator_ckpt 指向下载的检查点,并根据使用的后端设置 model_quant_use_transformer_engine:
- TransformerEngine 检查点(
model_te.pt):model_quant_use_transformer_engine: true - FourOverSix 检查点(
model_4o6.pt):model_quant_use_transformer_engine: false
setup_nvfp4_pipeline 处理两个后端的检查点加载、NVFP4 模块包装、权重物化、数据类型/设备放置以及流式管道 VAE 重定位——bf16 的 pipe.to(...) 快捷方式在此不安全,因为它会转换量化缓冲区。
import torch
from omegaconf import OmegaConf

from pipeline import CausalDiffusionInferencePipeline
from utils.config import normalize_config
from utils.inference_utils import prepare_single_prompt_inputs, save_video, setup_nvfp4_pipeline

prompt = "A compact silver robot walks through a clean robotics lab."

config = normalize_config(OmegaConf.load("configs/nvfp4/inference_nvfp4.yaml"))
device = torch.device("cuda")

torch.set_grad_enabled(False)
pipe = CausalDiffusionInferencePipeline(config, device=device)
setup_nvfp4_pipeline(pipe, config, device)
pipe.generator.model.eval().requires_grad_(False)

noise, prompts = prepare_single_prompt_inputs(config, prompt, device)
video = pipe.inference(noise=noise, text_prompts=prompts)
save_video(video[0], "videos/quickstart/sample_nvfp4.mp4", fps=24)
模型
| 模型 | FPS ↑ | 参数量 | VBench ↑ | 多镜头 |
|---|---|---|---|---|
| LongLive-1.3B | 20.7 | 1.3B | 84.87 | |
| LongLive-2.0-5B | 24.8 | 5B | 85.06 | ✅ |
| LongLive-2.0-5B-NVFP4-4Step | 29.7 | 5B | 84.51 | ✅ |
| LongLive-2.0-5B-NVFP4-2Step | 45.7 | 5B | 83.14 | ✅ |
许可证
本仓库采用 Apache 2.0 许可证发布。详情见 LICENSE。
引用
如果我们的工作对你有帮助,请考虑引用:
@article{longlive_2.0,
  title={LongLive2.0: An NVFP4 Parallel Infrastructure for Long Video Generation},
  author={Chen, Yukang and Wang, Luozhou and Huang, Wei and Yang, Shuai and Zhang, Bohan and Xiao, Yicheng and Chu, Ruihang and Mao, Weian and Hu, Qixin and Liu, Shaoteng and Zhao, Yuyang and Mao, Huizi and Chen, Ying-Cong and Xie, Enze and Qi, Xiaojuan and Han, Song},
  journal={arXiv preprint arXiv},
  year={2026}
}
@inproceedings{longlive,
    title={Longlive: Real-time interactive long video generation},
    author={Yang, Shuai and Huang, Wei and Chu, Ruihang and Xiao, Yicheng and Zhao, Yuyang and Wang, Xianbang and Li, Muyang and Xie, Enze and Chen, Yingcong and Lu, Yao and others},
    booktitle={ICLR},
    year={2026},
}
致谢
- Self-Forcing:我们在此基础上构建的 AR 训练代码库和公式。
- Wan2.2:本版本中使用的基础视频扩散模型组件。